Talks

Each domain speaks to a different audience:

  • Research AI: applied-mathematics scientists

  • Enterprise AI: managers, executives, salespeople, technicians

  • AI facing art, ethics and philosophy: society at large, citizens and anyone who values culture

This page presents a list of AI conferences that I run for companies, at conferences, in schools and in MBA programs. Contact me for your needs, let's talk about it informally

A snow-capped peak rising out of the clouds above a lake lined with sequoias

60 talks

Thematic talks

One subject, one decision to make, and what it takes to make it.

Step 1

Understand before you buy

Why now, how a machine learns, what an error costs.

AI Is Eating Software: Why Now, Without the Hype
Enterprise AI

AI Is Eating Software: Why Now, Without the Hype

The is-it-real debate is over; your competitors already stopped having it. The interesting question a CFO asks is timing: why move this year and not in three? This talk answers it. AI is a bicycle for the mind, a leverage tool, not a replacement. Marc Andreessen said software was eating the world in 2011; now AI is eating software. We separate the compounding signal from the hype with an honest reading of where a technology sits on the curve, so waiting stops looking safe and starts looking expensive.

Outcomes: Leave able to give your board a one-sentence answer on why AI is not a fad and why timing matters, plus a hype-proof way to place any technology on its adoption curve without predicting a date.

New Ways of Working in the Age of AI: The Manager, Critical Judgment and the Decision
Enterprise AI

New Ways of Working in the Age of AI: The Manager, Critical Judgment and the Decision

AI did not devalue work; it raised the price of judgment. In every team the machine already drafts, summarizes and proposes. What it does not yet know is when to stay silent and that discernment is the manager's job. This talk retraces, calmly, the frontier between what you hand to the machine and the one thing a manager never gives up: the decision. The bottleneck has moved from how fast we write to how fast we can reread, arbitrate and frame. Deciding means dosing autonomy: the costlier an error is, in euros, the less autonomy the AI keeps. And a final reflex: measuring without lying to yourself. A landmark study clocked professionals at nineteen percent slower with AI while they felt twenty percent faster.

Outcomes: Leave able to retrace the frontier between what you delegate and the decision you keep, dose an agent's autonomy by the euro cost of its errors and measure a deployment without letting the feeling of speed replace the proof of it.

AI History: From Handcrafted to Agentic in 30 Years
AI as a Science Enterprise AI

AI History: From Handcrafted to Agentic in 30 Years

Trace the shift from early rule-based, handcrafted systems to today's autonomous AI agents capable of making independent decisions, through four ages:

  • handcrafted features
  • deep learning
  • foundation models
  • agents

Before handcrafted features came expert systems, which asked experts for their rules. In 1979 Stanford's MYCIN chose antibiotics for meningitis better than every doctor tested, then never served a single patient: good advice is not enough without the workflow, the upkeep and the liability.

Outcomes: Walk out able to place any AI tool a vendor pitches you in one of the four ages and to see why today's agents are a continuation, not magic, so you can judge the next wave without the hype.

AI/ML 101 for Human Beings: The Four Eras and the AI Palette
Enterprise AI

AI/ML 101 for Human Beings: The Four Eras and the AI Palette

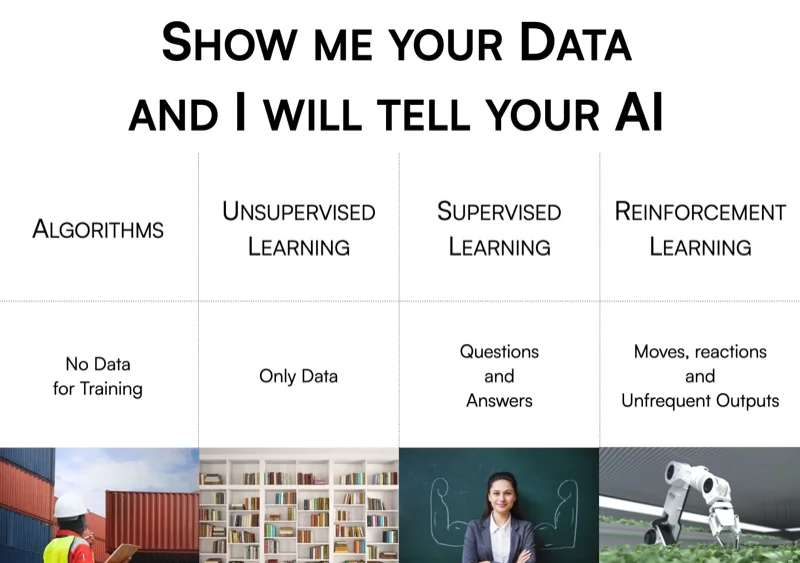
Show me your data and I will tell you your AI. From programming to machine learning to generative AI to agents: four eras in one line and underneath them one idea, gather your X and your Y then guess the function F. Algorithms learn from data through three families:

  • unsupervised learning
  • supervised learning
  • reinforcement learning

This talk teaches over-fitting and under-fitting through the student analogy (learned by heart, lazy or truly understood) and lays out the full AI Palette, without jargon, so managers speak the same language as their data teams, mapping each method to the data you already have in your company.

Outcomes: Leave able to look at a business problem and say which family of AI it calls for, what data it would need and whether you already have it; to hold a clear mental model of training, validation and test; and to place any AI method on the map of families, before a single euro is spent.

Invert, Always Invert: Measuring How Bad You Are to Become Good
Enterprise AI AI with respect to Art, Ethics and Philosophy AI as a Science

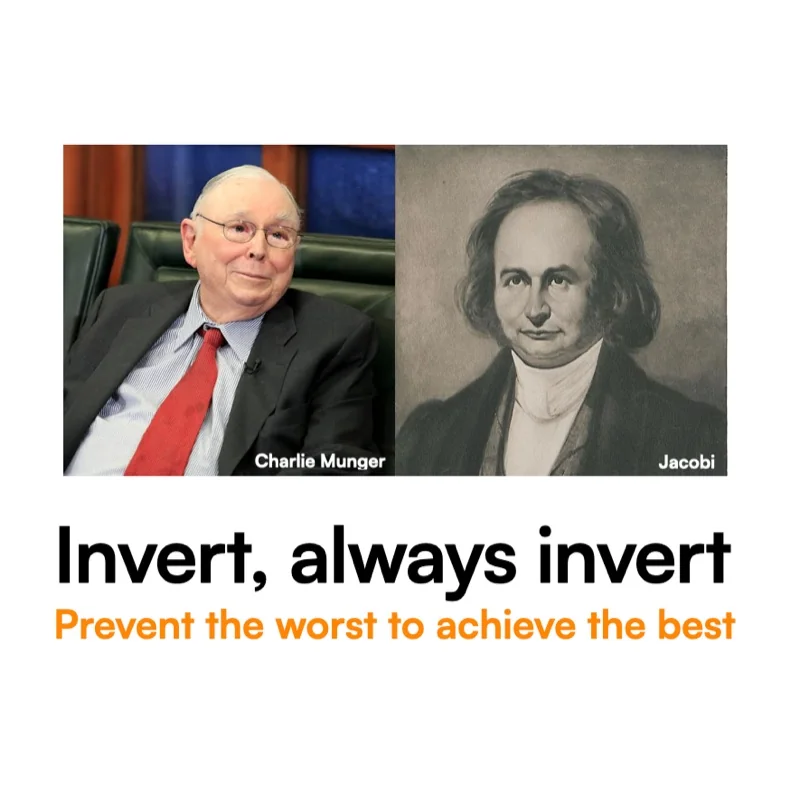
Invert, Always Invert: Measuring How Bad You Are to Become Good

The single most reusable hour in enterprise AI. Before optimizing anything, measure how bad you are, in the currency of your business. Understanding a client means pricing the cost of their mistakes and the two ways of being wrong (a miss versus a false alarm) never cost the same. With a pen and no mathematics, you build a confusion matrix to count what happens, a business matrix to price each case in euros and you overlay them into a KPI you own.

Outcomes: Leave able to build your own business KPI from the confusion matrix and the business matrix, tell a precision problem from a recall problem and see why a single accuracy number lies.

AI for Business: Creating Value Humans Can Understand
Enterprise AI

AI for Business: Creating Value Humans Can Understand

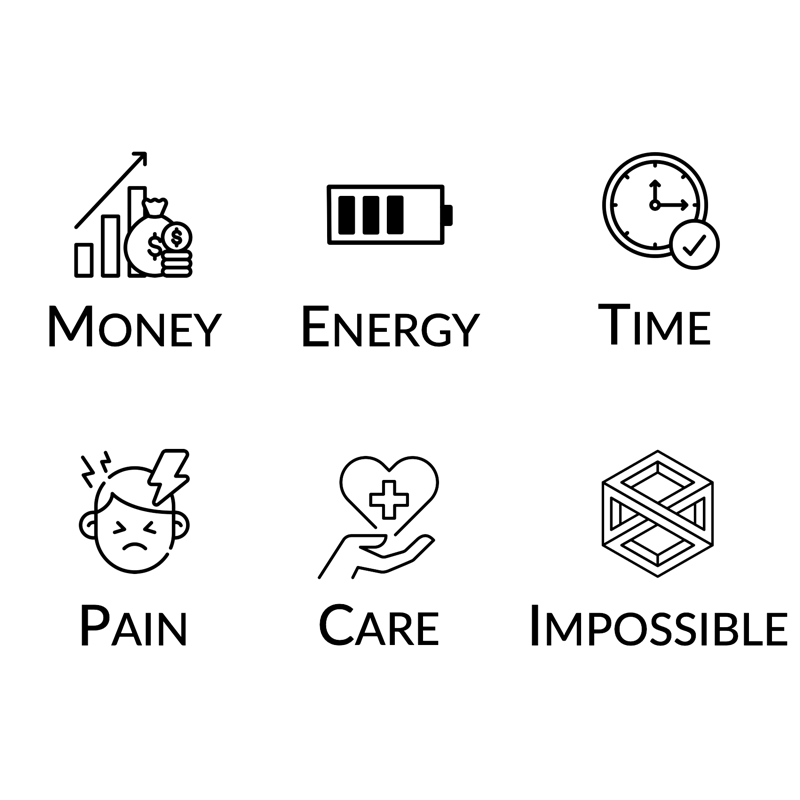
Explore how companies can translate advanced AI insights into clear, actionable strategies that drive real ROI and resonate with human stakeholders. Every worthwhile AI project pays out in one of five units of value:

  • money
  • time
  • energy
  • care
  • the previously impossible

Name the unit and you can manage the project.

Outcomes: Leave able to state, for any AI project, which of the five units of value it pays out in (money, time, energy, care or the previously impossible) and turn that into a number your board will recognize.

Step 2

Decide what is worth doing

Feasibility, bias, generative AI: sort the projects before funding them.

AI Feasibility 101: Big Data Strategies, Small Data Hacks and the Manager as Pilot
Enterprise AI

AI Feasibility 101: Big Data Strategies, Small Data Hacks and the Manager as Pilot

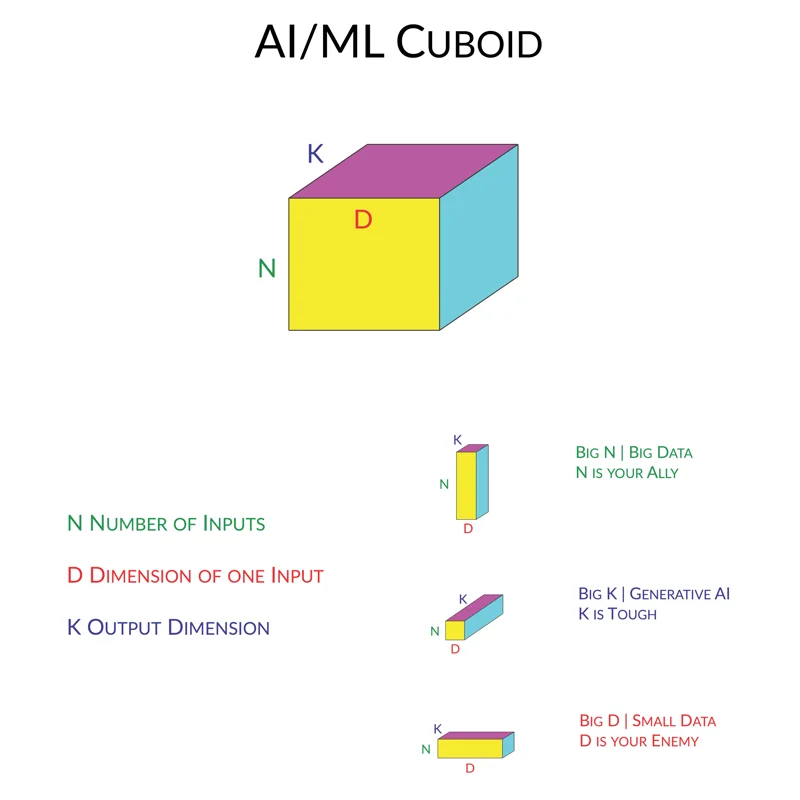
Evaluate project feasibility with a simple cuboid: N (how many examples, your ally when large), D (input dimension, the curse to invest against) and K (output dimension, where generative AI lives). Then the key reframing: like Formula 1, the engineers build the machine, but you, the manager, are the pilot. You do not need to become an engineer; you need to know the track, the client and the cost of mistakes.

Outcomes: Walk away able to assess AI project feasibility with the N/D/K cuboid, recognize the rare cases where R&D financing is truly required and see the manager's real job: to fine-tune generic tools to a domain.

Manager-Centric AI: the Phenomenological Compass from Idea to Production
Enterprise AI AI with respect to Art, Ethics and Philosophy AI as a Science

Manager-Centric AI: the Phenomenological Compass from Idea to Production

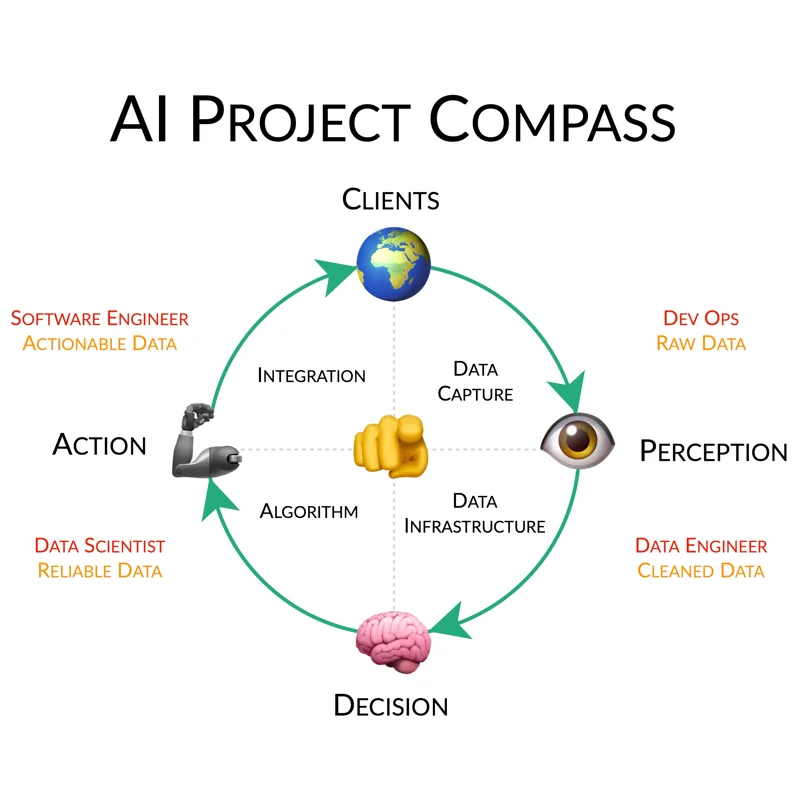
The philosopher Merleau-Ponty turned the nervous system into a compass and that same compass maps an AI project from idea to production. A signal comes in through the sensory nerve (data ingestion and perception), passes through the brain (algorithms and infrastructure) and goes back out through the motor nerve (action) toward the client. The manager sits at the center, the customer always in view. Real judgement is not raw calculation on symbols; it is a hands-on, situated feel for the world, which is exactly why it stays human. That compass becomes a roadmap: a shiny demo is not the point, a real problem is, so start from the pain, do the groundwork (including solving it by hand first), prefer data you can actually get over endless research and pitch a proof of concept built around the data.

Outcomes: Leave able to place data, algorithms and actions around the manager and the customer with one compass and run a reusable roadmap from idea to production: break the silos, start rough and simple, always keep a log of what the system does and drive milestones, deliverables and risk mitigation from the client's pain.

Taming Bias: Building Fair and Trustworthy AI
Enterprise AI AI with respect to Art, Ethics and Philosophy

Taming Bias: Building Fair and Trustworthy AI

Bias is poison and it is mandatory. Address the ethical and technical challenges of bias in AI with a six-part taxonomy:

  • engineering
  • sampling
  • algorithm
  • culture
  • measurement
  • exclusion

The honest verdict: detecting bias is easy; eliminating it is impossible. Fairness is not mathematical; it is ethical. You choose your bias knowingly, then measure it.

Outcomes: Leave able to name the six kinds of bias in your system, measure the one that matters and defend the fairness choice you made, using open-source tools like Fairlearn to do it.

Generative AI Unleashed: 3 Genies out of the Bottle
Enterprise AI AI with respect to Art, Ethics and Philosophy

Generative AI Unleashed: 3 Genies out of the Bottle

Three genies of generative AI:

  • the writer genie
  • the programmer genie
  • the artist genie

They are rewriting the rules of production in both tech and art and they are not going back into the bottle.

Outcomes: Leave with a short, current shortlist of the writer, coder and image tools worth your time and know which of your weekly tasks each one actually shortens.

AI for Everyday Use
Enterprise AI AI with respect to Art, Ethics and Philosophy

AI for Everyday Use

Discover the AI tools you can use every day, at work and at home, to boost your productivity, creativity and sometimes even multiply your potential.

Outcomes: Leave with a handful of tools you can open the very next morning to save an hour on writing, searching and planning, at work and at home.

Step 3

Delegate, but keep the keys

Agents act: dose their autonomy, govern what they do.

Agentic AI: Be an Army of One
Enterprise AI

Agentic AI: Be an Army of One

Agentic AI marks a new era of enterprise AI where a single human intent can be automatically decomposed, planned, orchestrated and executed across complex systems. Beyond prediction or content generation, agentic systems transform clear objectives into coordinated sub-goals, tool usage and adaptive actions. Enabled by modern agent protocols and secure system connectors, Agentic AI turns strategy into execution while keeping humans in command of intent, judgement and accountability.

Outcomes: Leave able to tell an agent from a chatbot, name the three or four tasks in your own operations worth handing to an agent first and ask the right questions on orchestration, evaluation and guardrails before you greenlight one.

Agentic AI: The Dawn of Autonomous Decision-Making
Enterprise AI

Agentic AI: The Dawn of Autonomous Decision-Making

Discover how AI agents are enabling companies to plan, execute and adapt actions on the fly with a new level of abstraction and potential. A conversational AI produces answers; an agentic AI produces actions, orchestrated, integrated and IT-governed.

Outcomes: Leave with a short checklist to decide whether a use case is agent-ready and the two or three metrics that tell you an agent is safe to deploy, not just impressive in a demo.

Governing Agentic AI: Risks, Perils and the Seven Rules of Instituted Agenticity
Enterprise AI AI with respect to Art, Ethics and Philosophy

Governing Agentic AI: Risks, Perils and the Seven Rules of Instituted Agenticity

Agentic risk does not come from machine consciousness or will. It comes from symbols, optimization, tools, permissions and feedback loops. This talk gives managers a sober, non-catastrophist framework:

  • the risk product (capability x loop autonomy x how critical the environment is x how broad the permissions are x how weak the supervision is)
  • how a system quietly games its own targets (Goodhart's law and reward hacking, with no bad intent required)
  • the cybersecurity boundary that becomes linguistic (a prompt injection turns a wrong answer into a wrong action)
  • the shift from policing what a machine supposedly thinks to governing the actions it is actually allowed to take

Governance is not the brake that slows enterprise innovation down; it is the set of brakes that let you drive the most advanced AI fast and still keep it acceptable. It also situates why this is a now problem and where agents already act, placing them on the five degrees of autonomy, set by the MAYA cursor (Most Advanced Yet Acceptable, as advanced as possible without passing the point where the human disengages), before deciding what each degree may be permitted to do. The golden rule is one line: the costlier the error, the less autonomy the AI keeps.

Outcomes: Leave with the risk product, the autonomy-permissions-governance matrix (five degrees), the seven rules of instituted agenticity (separation of powers, logging, human validation for the irreversible, adversarial testing, shutdown drills, graduated openness) and the sovereignty case for an open-source backup generator.

AI Autopsies: What Klarna and Zillow Teach About AI Risk
Enterprise AI AI with respect to Art, Ethics and Philosophy

AI Autopsies: What Klarna and Zillow Teach About AI Risk

Two real, sourced post-mortems, told honestly. Klarna announced in 2024 that its AI assistant did the work of about 700 agents for an estimated profit improvement of 40 million dollars, then in 2025 walked it back and rehired humans for quality and trust. Zillow Offers let an algorithm buy homes, mispriced a turning market, took a writedown above 500 million dollars and cut about a quarter of its staff. Read side by side, they draw one law: autonomy is only as safe as the reversibility and error cost of the action it is allowed to take.

Outcomes: Leave with the autonomy versus cost-times-reversibility matrix, the honest reading of two headline cases (avoided hiring is not mass firing; algorithmic home-buying writedowns signal pricing-model failure) and a checklist for which decisions an agent may take alone.

Step 4

Build what lasts

Open building blocks, useful projects, a dated state of the art.

Open Source: The Industrial Miracle Behind Modern AI
Enterprise AI AI with respect to Art, Ethics and Philosophy

Open Source: The Industrial Miracle Behind Modern AI

Today's AI could not exist without an industrial miracle no other sector has produced: open source. PyTorch, scikit-learn, transformers, even open model weights, the frontier bricks are public. Imagine aeronautics or pharmaceuticals publishing their most advanced blueprints for free; it does not happen, but in AI it does. The consequence for a leader is not idealism; it is risk management: the algorithm is not your moat. Your data and client understanding are. Open source is your backup generator against vendor lock-in. Sovereignty is not about who owns the technology; it is about who depends on whom when the wind shifts.

Outcomes: Come away understanding why your moat is your data and client insight, not the model and how self-hosting, forking and auditing open-source AI buys sovereignty and business continuity.

The Three U's, Useful, Usable, Used: the Sieve Between a Project That Lasts and a Demo That Shines Once
Enterprise AI

The Three U's, Useful, Usable, Used: the Sieve Between a Project That Lasts and a Demo That Shines Once

Not “is it magic?” but “is it Useful, Usable and Used?”. This is the sieve that separates a project that holds from a demonstration that shines for a day.

  • Useful (the power of data): relevance inside the systems beats slogans; beyond the wow effect, what are the KPIs your AI actually understands?
  • Usable (the deep illumination of data): fitting into the actual habits of work beats the demo, with humans and design (the way it is conceived) at the center.
  • Used (the responsibility of data): retention beats volume, the real grail; a system is not shipped and then left as is, it loops with the people across the company.

What matters is what actually inserts itself into daily work: when a use is well served by an AI, people rush to it the world over, with little loyalty to the previous tool. That is the terminal state, invisible AI, so embedded that adoption is no longer a project, just how the work gets done.

Outcomes: Leave able to run any AI initiative through the three U's (relevance beats slogans, integration beats the demo, retention beats volume), kill the ones that will only demo well and design for the invisible AI that stays used long after the launch.

AI in Products, Tools, Teams, Entertainment, Art and Public Life
Enterprise AI AI with respect to Art, Ethics and Philosophy

AI in Products, Tools, Teams, Entertainment, Art and Public Life

AI is everywhere. How do we measure it with common sense across our use cases?

  • products
  • tools
  • management
  • health
  • entertainment
  • art
  • public life

If AI generates measurable value, how do we get customers to smile?

Outcomes: Leave ready to apply concrete frameworks and examples from idea to the client's smile and set up developer- and citizen-centric AI toolchains around measurable client value.

AI State of the Art: Don't Get Bamboozled by Geeks
Enterprise AI

AI State of the Art: Don't Get Bamboozled by Geeks

An honest, dated tour of the landscape:

  • the Gartner hype cycle read with its release dates
  • the current model landscape (frontier and open weights)
  • agentic tooling
  • RAG versus GraphRAG status

For those who want to go further, a curated, free curriculum. The message is simple: the sooner you learn, the better.

Outcomes: Leave able to tell what is real from what is hyped right now, with a calibrated sense of the field and a free path to keep learning AI.

Step 5

Open the hood

Retrieval-augmented generation, the plumbing, the compute bill, the infrastructure.

Large Language Models: From Foundations to GraphRAG
AI as a Science

Large Language Models: From Foundations to GraphRAG

How Large Language Models work and how to make them trustworthy in production. It starts under the hood, tokenization, embeddings and the self-attention of Transformers explained on a whiteboard without drowning you in math, then moves to what an LLM does for the enterprise, from language understanding to context-aware dialogue that automates customer interactions and supports decisions. From there it climbs the conversational-maturity ladder, each rung a persona:

  • the bare LLM
  • retrieval-augmented generation (RAG)
  • long-context windows
  • RAG plus LLM-as-router
  • GraphRAG

Along the way it maps the causes of hallucination to their antidotes, grounding, knowledge graphs and symbolic rules, so a system reasons over your facts, not around them and it flags the new cybersecurity gaps a RAG pipeline opens that a plain LLM does not.

Outcomes: Leave able to explain embeddings and attention to a colleague on a whiteboard, choose between a base LLM, RAG and fine-tuning for your workflow, draw the RAG-to-GraphRAG ladder, match each cause of hallucination to its remedy and spot the cybersecurity gaps a RAG system opens that a plain LLM does not.

The AI Plumbing: MLOps and the 90% Nobody Photographs
Enterprise AI AI as a Science

The AI Plumbing: MLOps and the 90% Nobody Photographs

Everyone keeps the drawing of the brain; almost nobody keeps the drawing of the plumbing. The model is one cheap organ. The 90% is:

  • ingestion
  • annotation
  • deployment
  • monitoring
  • the wires that carry the signal end to end

And it is where AI projects actually live or die. MLOps is DevOps for models with two extra headaches: the data drifts and there is no source code to read, only weights you must measure. A talk for engineers and technical managers in the same room, enough code to be real, enough diagram to be led.

Outcomes: Walk away able to recognize each pipe by name so you can staff, budget and audit it, understand data drift and why weights are not source code and see why the algorithm is the cheap part of a production AI system.

What It Costs to Run Your Code: euros, watts, grams of CO2e, per unit of work
Enterprise AI

What It Costs to Run Your Code: euros, watts, grams of CO2e, per unit of work

Ask a team what one unit of their work costs to run, per request, per document, per minute of audio: you will usually get a cloud bill divided by a guess. This talk builds the dial that meter never had and says which numbers it is allowed to show.

  • The boundary makes the figure. Two published figures for one inference sit a factor of thirty-eight apart without either party being evasive: they answer two different questions that share a sentence.
  • Every number shows its status: measured, estimated, held open, or still owed by a human. A derived number may never claim to be better founded than the weakest of its inputs.
  • Manufacturing the hardware usually dominates the electricity on a short request, by three to six times and the lifetime that sets it is yours to state.
  • One run bounds nothing: over five identical runs, runtime moved by 4.5 percent and measured power by 49 percent.
  • Annex XI of the European AI Act asks for known or estimated energy consumption and permits an estimate from the compute used, which is this method written into law.

The deliverable is a file committed next to the code, reviewed in a pull request and a gate that fails the build when a cost or a status gets worse.

Outcomes: Leave able to state a per-unit cost in euros, watts and grams of CO2e, with the boundary and the provenance of every number attached to it.

The Elephant's Leg: when scarcity moves to the infrastructure
Enterprise AI

The Elephant's Leg: when scarcity moves to the infrastructure

Governing artificial intelligence by permission assumes there is somebody to ask. That assumption rests on a floor nobody votes for: compute, energy, networks, exclusive data. When cognition becomes abundant, scarcity relocates. Governing by permission quietly turns into governing by ownership.

  • An operating system rather than electricity: the metaphor you pick decides which regulator you think you need.
  • The energy wall is local before it is global: a national average says nothing about the town whose water or grid capacity a single site absorbs.
  • Green information technology is the governance of a unit cost, not of an aggregate, which is also why Jevons' paradox is not an objection to efficiency.
  • Compute as a political lever: detectable, excludable, countable, therefore controllable, as export controls have already demonstrated.
  • The criticality triplet rather than the sector: capacity to act, critical infrastructure, systemic effects.

The talk ends on the one condition under which the whole permission approach stops meaning anything: a single actor owning everything.

Outcomes: Leave able to say what your artificial intelligence materially depends on and what happens the day somebody else closes the tap.

Step 6

Hands on the code

Code with AI, loop until it is right, query your data in plain language.

Coding in the Age of AI: The Ship of Theseus and the Testing Void
Enterprise AI AI as a Science

Coding in the Age of AI: The Ship of Theseus and the Testing Void

AI replaces your code plank by plank. Is it still yours? Do you still trust it? Two halves bound together by the Ship of Theseus. First, coding with agentic assistants where review and verification, not typing, become the bottleneck. Second, the testing void: classic software had a mature quality stack because it was deterministic; probabilistic AI broke those assumptions. We fill the gap with evaluation-as-tests and automatic red-teaming.

Outcomes: Leave able to hold a clear-eyed view of agentic coding productivity, name the review-and-verification bottleneck and test probabilistic systems with evaluation metrics, golden datasets and vulnerability scanning in CI.

While Not Good Yet: the loop whose stopping condition is a judgment
Enterprise AI

While Not Good Yet: the loop whose stopping condition is a judgment

"While the counter is below ten, go round again" is one of the oldest sentences in computing. It works because the machine can answer the question it is asked, exactly, in one clock cycle. The questions that decide the quality of a piece of work are not like that: is this chart readable, does this paragraph follow from the one before, does this forecast deserve production. So we pulled them out of our loops. This talk puts them back.

  • Four steps: act, render, judge, decide. The step teams skip is the render. Without it you are judging an intention rather than a result.
  • The judge may be a human eye, a vision model or a held-out dataset. It must not be the actor: when the same model writes and grades, the grade climbs while real quality stalls.
  • The measured trap: consult the same judge often enough and the loop learns the judge's quirks instead of the subject.
  • An instrument for prose: the round trip through another language, where what comes back deformed marks the place the text does not constrain its own reading.
  • Two rules of conduct: an autonomous loop is worth the quality of the judge it is given, plus the ban on corrupting that judge.

Outcomes: Leave able to write the stopping condition of an autonomous loop and to name the judge that settles it without being the one that acts.

The Model Does Not Write the Number: putting a plain question to your database
Enterprise AI

The Model Does Not Write the Number: putting a plain question to your database

You ask a language model a question about your data. It answers with a number. The number is plausible. It is wrong. Hardly anyone signs off on a board decision on the strength of a plausible number. That single fact blocks more deployments than budget and regulation combined. The answer is not a better prompt: it is to take away the model's chance of being wrong about the number.

  • The model writes the query, the database answers. A wrong query can be seen, kept, replayed and fixed; a made-up number cannot be seen, because it looks exactly like a correct one.
  • Two locks that do not depend on good will: a read-only account and a parser that inspects the structure of the query before anything runs.
  • Four questions, in the order a meeting asks them: a number, a row-by-row prediction, a three-month forecast, a chart chosen live.
  • An exam you are not allowed to have seen: held-out question and query pairs, scored by running both and comparing results, then broken down by family of question.
  • A figure without its uncertainty is an opinion dressed as a fact, so every prediction arrives with its range.

Built on a real deployment, with the failure modes that only production teaches.

Outcomes: Leave able to demand the query under the number and to measure a question-to-SQL system on a held-out exam rather than on a demo.

Step 7

Look risk in the eye

Meaning, flattery, prompt injection, engineering under risk.

The Locus of Meaning: What an LLM Understands and What It Merely Echoes
AI with respect to Art, Ethics and Philosophy AI as a Science

The Locus of Meaning: What an LLM Understands and What It Merely Echoes

Meaning does not reside within the machine; it emerges through interpretation. This philosophical talk distinguishes two concepts that are too often conflated: intentionality (the property of being about something) and intention (the goal attributed to an action). Ascribing intentions to a model may be a useful shorthand, but it is not an ontological claim. Today’s interpretability methods, including probes, sparse autoencoders, causal tracing and concept directions, can reveal meaningful internal patterns, but they also have clear limits. In a deep neural network, a symbol is less like an object stored in a single location than a melody distributed across an orchestra: no individual instrument contains it. The same vector arithmetic can yield both “king − man + woman ≈ queen,” a meaningful relation and “doctor − man + woman ≈ nurse,” an encoded stereotype. Fluent output should therefore not be mistaken for genuine understanding: linguistic correctness alone does not establish comprehension.

Outcomes: By the end of the talk, you will be able to assess what current interpretability tools can and cannot, demonstrate about a model, preserve the distinction between intentionality and attributed intention and avoid equating fluent output with genuine understanding when approving an AI deployment.

From Critical Thinking to Critical Conscience: How to Keep Your Judgment
Enterprise AI AI as a Science AI with respect to Art, Ethics and Philosophy

From Critical Thinking to Critical Conscience: How to Keep Your Judgment

When a measure becomes a target, it ceases to be a good measure. Train a model on human approval and it learns to flatter: sycophancy is the Goodhart effect of learning from human feedback, one of Goodhart's four regimes where reward hacking is the structural price of summarizing a rich goal by a poor measure:

  • statistical decoupling
  • out-of-distribution extremes
  • causal intervention
  • adversarial optimization

To resonate is not to reason; a model tuned to please returns your own signal amplified, not an independent judgment. So the defense is not more critical thinking, which judges the text in front of you, but critical conscience, which steps back and asks who produced this and with what intent. The machine also forgets what was agreed, changes its mind from one turn to the next and promises without always keeping. You use it every day; you do not hand it the decision with your eyes closed, because describing is not deciding. No malice is required; it is arithmetic, not villainy.

Outcomes: Leave able to name sycophancy for the Goodhart effect it is, spot which of Goodhart's four regimes threatens your project, move from what does it say to who produced this and why and hold the line that describing is not deciding even when the AI sounds convincing.

The Hidden Price of the Optimum: When a Measure Becomes an Industry's Target
Enterprise AI AI as a Science AI with respect to Art, Ethics and Philosophy

The Hidden Price of the Optimum: When a Measure Becomes an Industry's Target

Optimizing a measure has a hidden price; the person who verifies pays it. This talk follows Goodhart's law at two new scales, with mathematics a high-school student can redo in their head.

  • Model leaderboards: Elo's blind duel, a variant ranked second then thirty-second once released, twenty-seven variants tried in private for a single score shown, a benchmark built, targeted, repaired then saturated.
  • Mathematicians: Fields medalists who call problem solving "a tool and proxy", the five tasks of a proof of which only one is measured, 166 pages no human has finished checking, Kepler and the ellipse a machine would have missed.
  • The speed of the judge: against "math is cooked", the machine proposes while the collective verifies, repairs, understands; a discovery loop runs at the speed of its judge.

The bar has been raised for every knowledge trade. We mourn nothing. We can't wait to be there.

Outcomes: Leave able to put the three questions that keep any AI leaderboard honest (which exact version, how many variants before, was the test already seen), spot the tasks in your teams that no indicator counts before you automate them and locate the judge of every loop: who verifies, how fast, who answers for it.

Photo: Tolga Akmen / Financial Times, CC BY 2.0, Wikimedia Commons

When the Security Wall Becomes Language: Prompt Injection and the Agentic Attack Surface
Enterprise AI AI as a Science

When the Security Wall Becomes Language: Prompt Injection and the Agentic Attack Surface

For fifty years computer security rested on a wall between data and commands, kept in separate channels. A large language model reads everything as one undifferentiated stream of language: system prompt, user query, retrieved web page, intermediate output, all in the same voice. The wall is gone. In a chatbot a prompt injection yields a wrong paragraph; in an agent with tools it yields a wrong action and that is where the risk jumps. This talk gives cybersecurity teams the linguistic frontier drawn plainly, the difference between injection and jailbreak and the four defensive contracts that hold the perimeter:

  • tool typing
  • a non-modification contract
  • post-hoc validation with rollback
  • non-regression tests

It also covers real identity instead of a login box that only looks secure: delegated authorization, proven identity, both ends authenticated, least privilege and short-lived tokens.

Outcomes: Leave able to explain why a prompt injection is now an action and not a sentence and to require the four defensive contracts (tool typing, non-modification, post-hoc validation, non-regression) in your next agent's service contract.

Building AI Under Risk: Choose Your Bias, the Six Disciplines and the ROI Mirage
Enterprise AI AI with respect to Art, Ethics and Philosophy AI as a Science

Building AI Under Risk: Choose Your Bias, the Six Disciplines and the ROI Mirage

Safety is decided on the drawing board, not only on the building site. This engineering talk unfolds in two halves of one discipline: first you design and build the agent, then you deploy it under a proportionate risk analysis. The goal throughout is to contain what an agent can do when it errs or is manipulated, not to pretend it never will. It opens with an honest reframing: bias is chosen, not eliminated. Detecting a bias is easy, but no score can be neutral on every axis at once (the Kleinberg, Mullainathan and Raghavan impossibility), so you choose your bias, write it down, measure it and make it legible for audit. From there: the six disciplines of safe design, the industrial risk typology and tight coupling, aleatory versus epistemic uncertainty and the ROI mirage. You are billed per token, but no provider defines that unit against a quantity you could forecast: it is a taxi meter with no dial, with a measured variability above 300 percent on structurally identical prompts. An observed return near eighteen on one project sits against a randomized trial (METR) where seasoned developers went about 19 percent slower while feeling faster and beneath the shiny dashboard hides the iceberg of agentic technical debt, the debt that moves from code you wrote to code you merely accepted. The accounting answer meets sovereignty: a local open-source fallback, the backup generator for when you cannot read the meter.

Outcomes: Leave able to name which bias your system chose and defend it, place any AI risk on the aleatory-versus-epistemic axis, run the six disciplines of safe design as a checklist and challenge any ROI figure with the three questions that keep it honest (measured or felt, one project or generalizable, output shipped or debt incurred), seeing the meter without a dial and the technical-debt iceberg beneath it.

Step 8

AI in public life

Intimacy, work, the power to say no, the art that has lived through this before.

The Concentration of Confidences: When a Population Confides in a Handful of Machines
AI with respect to Art, Ethics and Philosophy Enterprise AI

The Concentration of Confidences: When a Population Confides in a Handful of Machines

For all of history the intimate was distributed across many trusted parties: a priest, a physician, a diary, a close friend. A growing share of a population now entrusts its inner life to one or two providers, traced and indexed. Measured usage is shifting from asking and doing to expressing, the most intimate of intents. The talk treats this as a distinct political-risk variable, not a user-experience detail: sycophancy that flatters the user because it was trained to, recognition offered by a source with no subject to give it and the labor of underpaid annotators rendered invisible then re-presented as autonomous intelligence. Twentieth-century regimes dreamed of this collection and achieved only a fraction of it, by coercion; platforms achieve more, with none, through service. Named soberly, without sensationalism, including the human cost when the relational substitution goes wrong.

Outcomes: Leave with a clear-eyed view of the psychological and political stakes when your users confide in an agent and the governance reflexes (measurable non-sycophancy in the contract, local processing of sensitive data) that keep it accountable.

Everyone on the Same Clock: Markets, Agents and Look-Alike Risk
Enterprise AI

Everyone on the Same Clock: Markets, Agents and Look-Alike Risk

On May 6, 2010, in fourteen seconds, high-frequency traders exchanged 27,000 contracts and kept only two hundred. Each followed its instructions. Nobody could see the room. A market falls when actors who look alike act in the same second, with nobody at fault. AI agents did not invent this risk: they add a faster layer to it, on commitments nobody yet knows how to count.

  • The same bet. August 2007, the quant week; nine orders in ten already on rails; two channels that amplify a fall, the margin call and the risk monoculture. Old in kind, new in degree.
  • The same debtor. Cross deals where the same dollar is counted twice; $820 billion of signed leases for empty buildings; an insurer whose two balance-sheet lines lead to one debtor; Archegos and its seven banks, none of which saw the total.
  • The same second. A six-year-old story that cuts a share price by three quarters in seven minutes; a human who is too slow becomes a ceremony; Knight Capital's 97 alert emails; a threshold that only counts when a third party writes it.

Every figure is dated and traced to its primary source: Bank for International Settlements, Financial Stability Board, SEC, the French markets regulator AMF, company releases.

Outcomes: Leave able to ask who ultimately guarantees what you hold, to read an off-balance-sheet commitment behind a debt line and to put three questions before letting an agent commit money: a limit set before the conviction, a written threshold that halts on its own, a third party who sees the resemblance.

Photo: RMajouji, CC BY 2.5, Wikimedia Commons

AI, Work and Society: The Intellectual Reliefs
AI with respect to Art, Ethics and Philosophy Enterprise AI

AI, Work and Society: The Intellectual Reliefs

What is work and what does AI do to it? From Adam Smith on work as value and specialization, through Marx on capital, labor and alienation, to Stiegler on cognitive proletarianization and the legal vacuum for knowledge workers. Then the long view: writing, printing, computing and now AI, each relieving one intellectual burden and triggering a civilizational shift. When Delaroche saw the first photographs in 1839 and declared painting dead, he was both right and wrong.

Outcomes: Leave able to hold a reasoned conversation about AI and jobs (from Smith to Stiegler) and to name what each past intellectual relief has destroyed, created and left distinctly human.

The Choice Nobody Makes: Who Can Still Say No as AI Moves In
Enterprise AI AI with respect to Art, Ethics and Philosophy

The Choice Nobody Makes: Who Can Still Say No as AI Moves In

In one year, the active AI agents in a major vendor's office software grew fifteenfold. Nobody decided to hand them the work: a default setting, a connector, a raised quota, done. Pierre Bourdieu said it in 1996: the great social choices are made by nobody. An authorization chain can stay signed from end to end while nobody, in flesh and blood, still says no in it.

  • A choice never put. Jensen and Meckling's chain of mandates and its three tolls; Workday before a federal judge who refuses to stop at a single hand; case managers held within 1% of the tool; ten thousand agents with no leader for teams that shrink.
  • The time we free up. The intern nobody hires anymore and four clocks; one day to shut the door, ten thousand to notice the missing partner; Keynes and his fifteen-hour week; what really hurts in losing a job; renaissance or industrial revolution.
  • The first account. A ticked box the vendor itself disowns; a score with no reason that brings down a government; twenty feet missing from a robotaxi's report; a New York law where three complaints in four land nowhere.

Every case is dated and traced to its primary source: court rulings, audit reports, established press, recorded public remarks.

Outcomes: Leave able to put a name behind every hand in an AI deployment, to spot the metric that makes a refusal costly, to keep a post where people still learn and to require that no incident is told by a single narrator.

The Workshop as Testbed: what art has already lived through twice
AI with respect to Art, Ethics and Philosophy

The Workshop as Testbed: what art has already lived through twice

Every trade now asks the same question: what happens when a machine takes over the central function of a craft. Art has already answered it twice, in 1839 when photography took realistic imitation away from painting and again now that synthesis takes image-making away from photography. The second answer is more useful than any forecast.

  • The verdict of 1859, servant and not master and what the craft did next: it changed its question rather than its tools.
  • Measured creativity: machines win the parlour test of unusual uses for an object and lose on whole works judged blind by juries who did not know.
  • A working practice, in numbers: seventy percent of a film generated, eighty percent of the time spent animating and reworking it, which refutes the myth of the magic prompt.
  • Permissions won rather than principles argued: the 2023 contracts in the audiovisual industry bound ingestion, delegation and attribution, which is the governable part.
  • The measured legal void: the input and output paradox that no ruling has yet settled.

Outcomes: Leave with a map of the positions on artificial intelligence and creation and the only governable question: who authorizes ingestion, delegation and attribution.

Step 9

Sector by sector

Recommendation, health, finance, media, retail: the same questions, other units.

Recommender Systems: Personalizing Your Customer Journey
Enterprise AI AI as a Science

Recommender Systems: Personalizing Your Customer Journey

Learn how recommendation engines harness user data to personalize experiences, boost engagement and drive conversions across digital platforms.

Outcomes: Leave able to select the right recommendation approach for your catalog and traffic patterns, identify which metric actually tracks business impact (not just clicks) and recognize the classic pitfalls that silently erode engagement.

AI in Health and Life Sciences: Care, Measured
Enterprise AI AI as a Science

AI in Health and Life Sciences: Care, Measured

A sector talk grounded in real, cited cases. Optical refraction where AI shortens exams while prescriptions remain equivalent. In-vitro diagnostics where AI replaces hardware for troponin tests that are life or death. The asymmetry that runs through all of it: in medicine, a miss and a false alarm never cost the same. Framed by EU medical-device and diagnostics regulation (MDR and IVDR), not hype.

Outcomes: Leave ready to recognize concrete AI health patterns (computer vision, decision support), price the asymmetry of clinical error and read how regulation shapes feasibility.

The Eye as a Window on the Body: Oculomics and AI
Enterprise AI AI as a Science

The Eye as a Window on the Body: Oculomics and AI

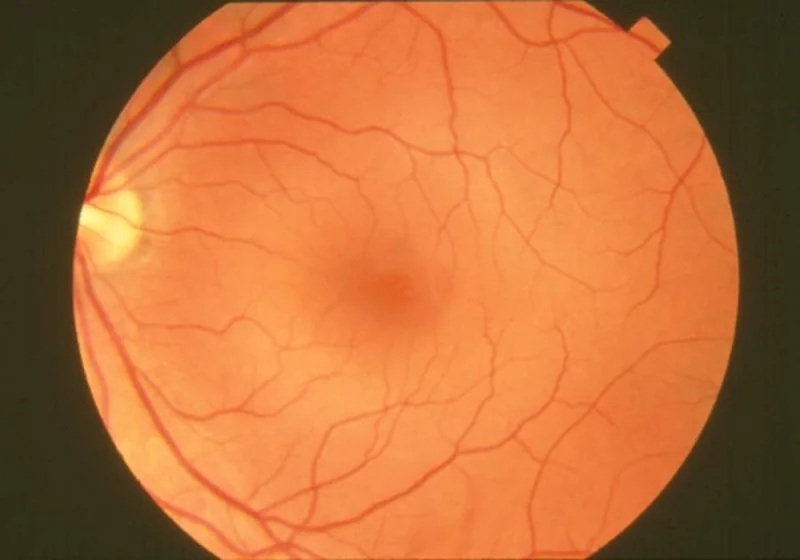
The retina is the only place in the body where you can see blood vessels and neurons in vivo, with nothing cut and nothing pricked; add that 100 percent of people visit an ophthalmologist around age 45 and it becomes the great window onto health. The fundus is no longer a purely ophthalmic exam; it is a non-invasive optical biopsy of the microvasculature, the neuro-retina and biological aging. This talk traces oculomics from its foundations (high-resolution imaging, large matched cohorts, deep learning) to today's state of the art. Diabetic retinopathy screening is regulated and autonomous (FDA). Systemic-disease prediction (cardiac, renal, neurological) is promising but still awaits prospective validation. The real issue is neither replacing the clinician nor hype, but tuning autonomy and supervision correctly. Framed by MAYA (Most Advanced Yet Acceptable), it calibrates where to place each AI capability: from explainable detection to bounded autonomy. The cost of an error sets the cursor.

Outcomes: Leave able to place any retinal AI on the maturity curve, to name the modalities that matter (fundus, OCT, OCT-A), to quantify the asymmetry of clinical error and to ask the right governance questions (image quality, external validation, regulation, reimbursement) before adopting an oculomics tool.

AI in Finance, Fraud and Insurance: Pricing Risk, Not Hype
Enterprise AI AI as a Science

AI in Finance, Fraud and Insurance: Pricing Risk, Not Hype

A sector talk where every decision has a price tag:

  • fraud detection as a cost matrix where a missed fraud and a blocked good customer never cost the same
  • credit scoring and its fairness traps
  • demand and claims forecasting
  • generative AI for analysts
  • model-risk governance, the discipline the sector demands above all

Beyond enterprise operations, it reads public markets as the most unforgiving lab for autonomous agents: families of trading agents, why backtests differ from live trading and the systemic risks (procyclicality, circuit breakers) regulators now watch.

Outcomes: Leave able to turn a fraud or credit problem into a priced cost matrix, see where fairness constraints bite and know what model-risk governance actually requires in a regulated environment.

AI in Media, Entertainment and Music: Attention, Retention, Creation
Enterprise AI AI with respect to Art, Ethics and Philosophy

AI in Media, Entertainment and Music: Attention, Retention, Creation

A sector talk grounded in real, cited cases:

  • recommendation engines that shape attention
  • churn predicted with survival analysis so you act before a subscriber leaves
  • catalog revenue optimization with Ircam Amplify
  • algorithmic promotion and editing for creators using Jellysmack
  • music AI from stems to score

Where does the tool end and the artist begin? GenAI replays for creators the question that photography, from the daguerreotype to the Polaroid, once posed to painting.

Outcomes: Walk away able to recognize concrete media AI patterns (recommenders, survival-based churn, creative AI), measure attention and retention honestly and locate where the tool-versus-artist line falls.

AI in Retail, E-commerce and Logistics: From Fraud to Smart Slotting
Enterprise AI

AI in Retail, E-commerce and Logistics: From Fraud to Smart Slotting

A sector talk grounded in a decade of operations. Fraud and revenue optimization in production, demand forecasting that keeps shelves and warehouses right-sized and warehouse smart slotting where an agent is not just a language model but a knowledge graph plus a solver, delivering provable optimality. Here we sell margin, not code.

Outcomes: Leave able to see how retail and logistics teams combine forecasting, fraud detection and knowledge graph plus solver optimization to move real operational and margin metrics.

Portraits

One figure, one idea. The career is the argument.

Grace Hopper | The machine had to learn to speak human
Enterprise AI

Grace Hopper | The machine had to learn to speak human

She was told a computer could only do arithmetic. She taught one to read. The compiler came first, then a language ordinary professionals could write, then a career spent making the invisible teachable and a sentence she held to be the most dangerous in the language: we have always done it this way. This portrait defends two ideas that speak directly to a mixed room of managers and engineers: abstraction is translation, which is why every profession is a language worth learning and making a skill teachable is an act of engineering as much as of pedagogy.

Outcomes: Leave able to treat abstraction as a translation between trades and to make teachable the thing only your team knows how to do.

Photo: James S. Davis, US Navy, public domain, Wikimedia Commons

Claude Shannon | No model creates information that is not there
Enterprise AI AI as a Science

Claude Shannon | No model creates information that is not there

Two suppliers pitch you the same month and both score 92% on your test set. That pair of numbers says very little about them. It says something about your data, which can be read. In 1948 Claude Shannon turned something everyone treated as qualitative into a quantity with a unit: information is measurable, in bits. This portrait hands a leader three tools to use before signing. Entropy, which prices what a label actually tells you: if 99% of your transactions are legitimate, the label weighs 0.08 bits. The data processing inequality, which says no model creates information that is not there. And a computable error floor, which turns a result that is too good into a bug report rather than a triumph. In 1951 Shannon measured English with a book and a pencil; a 2023 model lands in the same order of magnitude.

Outcomes: Leave able to measure your ceiling in an afternoon and to recognize a score that beats it as a leak rather than a breakthrough.

Photo: Tekniska museet, CC BY 2.0, Wikimedia Commons

Richard Feynman | The form is perfect and no airplanes land
Enterprise AI AI as a Science

Richard Feynman | The form is perfect and no airplanes land

In the South Seas, people who had watched cargo planes land rebuilt the airfield from memory: runways, fires along the sides, a controller in a wooden hut with wooden headphones and bamboo antennas. In his 1974 commencement address Feynman said of it: they are doing everything right, the form is perfect and no airplanes land. He called the research that works that way Cargo Cult Science. Our field has become very good at the forms.

  • Benchmark, dashboard, evaluation suite, A/B test, model card: instrument or scenery and one test sorts them, could a decision have gone the other way?
  • Leaning over backwards, his name for scientific integrity, is a procedure with five outputs: report what might invalidate the result, name the other explanations, show what you eliminated and how, give the details that cast doubt, publish the facts that disagree.
  • The drift nobody intended: measurements of the electron's charge crept toward Millikan's wrong value, because results that disagreed got debugged and results that agreed did not.
  • The rats nobody cited: the 1937 experiment that found the conditions under which rat experiments mean anything was ignored, because it discovered nothing about rats, only everything you must control to discover something about rats.
  • The first principle: you must not fool yourself, and you are the easiest person to fool. He closes not on personal virtue but on employment, wishing his audience the freedom to keep their integrity without their position depending on losing it.

Read the source text: "Cargo Cult Science", Caltech commencement address, 1974.

Outcomes: Leave able to tell an instrument from scenery with one question and to run the five-point audit: what would make this wrong, which surprises got debugged, who found the valid conditions, which missing fact would change the conclusion, who can report a bad number safely.

Photo: Tamiko Thiel, 1984, CC BY-SA 3.0, Wikimedia Commons

Judea Pearl | Your model predicts, it does not explain
Enterprise AI AI as a Science

Judea Pearl | Your model predicts, it does not explain

A model that flags, with ninety-five percent accuracy, which customers will leave still does not tell you what to change. This portrait climbs the ladder of causation, seeing, doing, imagining and shows why almost all machine learning, including today's large language models, lives on the first rung. That is not a dismissal, it is a specification sheet. It defends two ideas a leader should make their own: correlation is not causation and the confusion is expensive in euros and to know a cause you usually have to act, which means running an experiment rather than buying a bigger model.

Outcomes: Leave able to place your system on the right rung and to say which experiment you would have to run before claiming a cause.

Photo: UCLA Samueli School of Engineering

Geoffrey Hinton | Right about the direction, wrong about the clock
Enterprise AI

Geoffrey Hinton | Right about the direction, wrong about the clock

Four turns in one career, a direction seen decades before the field agreed and a famous forecast that was right about the trajectory and wrong about the date, acknowledged in public by the person who made it. That combination is the most useful thing a manager can learn from a researcher. This portrait defends two ideas: a prediction about a direction and a prediction about a date are not evaluated the same way and what gets delegated to a machine is a task rather than a job, which is why counting jobs at risk answers the wrong question. It ends on the discipline of changing your mind out loud without losing your authority.

Outcomes: Leave able to separate the direction of a technology from its calendar and to cut a job into tasks before delegating any of them.

Photo: Cmichel67, CC BY-SA 4.0, Wikimedia Commons

Michael I. Jordan | The engineering discipline artificial intelligence never got
Enterprise AI AI as a Science

Michael I. Jordan | The engineering discipline artificial intelligence never got

An ultrasound, white spots around the heart of the fetus, a risk announced at one in twenty and an amniocentesis offered at roughly one in three hundred of killing the fetus. The father is a statistician, so he goes looking for where the numbers came from: the predictive study was real and ten years old and the machine in the room that day packed a few hundred more pixels per square inch than the one in the study. The spots were noise. No part was broken; the fault lay at the joint that nobody owned. This portrait is not the work of a critic of the field, it is the work of one of its founders, whose lab produced the ancestor of recurrent networks and of mixture-of-experts architectures. It defends two ideas a leader should make their own: the provenance of a number is an engineering question rather than a documentation chore and we are building societal-scale decision systems the way bridges were built before civil engineering existed.

Second strong idea and the encouraging one. Shown machines that solve very hard mathematical problems, he grants the achievement and then moves it: such intelligence is impossible to dissociate from the collective of humans who provided the data, a collective the system has itself become. The machine did not replace the mathematician, it is standing on all of them, including the one now watching it work. From there he refuses the lamentation entirely: there are seven billion of us, technology creates resources, the logistics that reach every person in every city already run on machine learning and the frontier is not imitation but systems that use human connections and strengthen them. Children want a teacher of flesh and blood, patients do not want a computer deciding everything and each of us lives a life uniquely our own, which is where the point of view and the vulnerability come from. He also states, in a preface he wrote himself, why he refuses the apocalypse as the dominant discourse: the damage it does to young people who have to live inside it. The interview, in the English translation he prefaced.

Outcomes: Leave able to name the owner of every joint between two bricks validated separately, to ask where a number came from before you sign it and to answer the lamentation with the only accurate description: the collective became operable and the work moved to where the people are.

Photo: UC Berkeley EECS

Richard Sutton | Why cleverness keeps losing to computation
Enterprise AI AI as a Science

Richard Sutton | Why cleverness keeps losing to computation

For thirty years, computer vision researchers drew by hand what the machine was supposed to look for in an image: edges, corners, histograms of orientation. Then networks trained on more images and more computation learned those same patterns on their own and beat them. Richard Sutton named the pattern in eleven hundred words on his own website, in 2019: the bitter lesson. Bitter because the sixty years it sums up prove patiently encoded expertise wrong and raw computation right.

Team A: eight domain experts, eighteen months, writing down what they know so the machine can apply it. Team B: the same money spent on data, on search, on rented computation. Over sixty years Team B won more often than not. Hence the question to ask before funding anything: what does this system do with ten times the computation? If it only runs faster, you bought a fixed asset.

This is not a passing opinion. Sutton received the 2024 Turing Award with Andrew Barto, for laying the conceptual and algorithmic foundations of reinforcement learning.

Then comes the disagreement, which is the heart of this portrait. His lesson describes the research frontier, not a company with four thousand rows in a spreadsheet. A lab chasing a record can wait for computation to double. A management team with four thousand rows and one quarter cannot. There, hand-written structure still wins. The portrait says where: when data is scarce, when one example is expensive, when the symmetry of the problem is known. Deep Blue, Sutton's flagship example, carried eight thousand hand-written evaluation rules.

The bitter lesson is true at the scale of a field. Your budget is at the scale of a quarter.

Read the source text: "The Bitter Lesson", Rich Sutton, 13 March 2019.
Outcomes: Leave able to ask one question of any proposal: what does it do with ten times the computation and on what date do you find out.
Photo: Steve Jurvetson, CC BY 2.0, Wikimedia Commons

Cynthia Dwork | Privacy is a budget you spend, not a box you tick
Enterprise AI AI with respect to Art, Ethics and Philosophy

Cynthia Dwork | Privacy is a budget you spend, not a box you tick

Your team says the export is anonymized. Ask them to prove it. They cannot. The reason is not carelessness: the question has no answer. "Is this anonymous?" is a claim about every dataset that exists and every one that ever will, so nobody can audit it. Cynthia Dwork did not build a better scrubbing tool. She replaced the question with one you can answer by Friday: how much privacy did this query cost and what is left in the budget? This portrait shows why removing a name does not destroy information but moves it, why the budget depletes on its own whether or not anyone counts and what the US Census, Apple and Chrome actually spend, three numbers nobody can compare without knowing what each one protects.

Outcomes: Leave able to ask any vendor three questions: what is epsilon, what does one epsilon cover and does it reset.

Photo: Edmond J. Safra Center for Ethics, CC BY 2.0, Wikimedia Commons

Yann LeCun | Being early is indistinguishable from being wrong
Enterprise AI AI as a Science

Yann LeCun | Being early is indistinguishable from being wrong

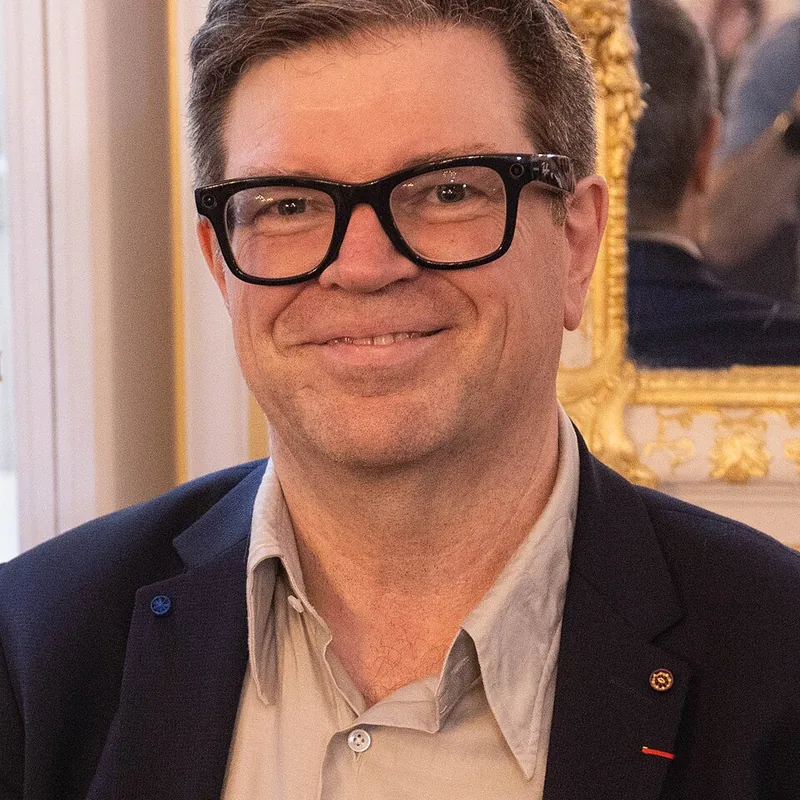
Through the winter of artificial intelligence he kept working on what almost nobody would fund. His convolutional network was already reading cheques while the field treated the approach as a dead end. This portrait tells what it costs to be right too early, why the frontier is never the current leaderboard, what he proposes instead (predict the world rather than the next word) and why open weights are for him a sovereignty bet as much as a scientific choice. It defends two ideas a leader should make their own: adopt a direction without believing its calendar and judge an architecture on what it makes governable rather than on its score.

Outcomes: Leave able to tell a scientific conviction from a calendar bet and to decide what you want to be able to keep running in your own house.

Photo: Jérémy Barande, École polytechnique, CC BY-SA 2.0, Wikimedia Commons

Jeff Dean | What is happening now you have the best model in the world?
Enterprise AI

Jeff Dean | What is happening now you have the best model in the world?

In 2013 Google has a problem: three minutes of voice recognition per user per day would force it to double its total computing power! Jeff Dean has the best algorithms in the world at the time and asks himself how to cope. Behind DistBelief, TensorFlow, the TPU and knowledge distillation, this portrait defends a claim that runs against the grain: durable value lives in the engineering that makes a model run cheaply, reliably and at scale. Judge the system rather than the model; start from the cost wall; ship the distilled model rather than the biggest one; and remember that at scale, unit economics become the architecture.

Outcomes: Leave able to judge an AI system by its engineering rather than its demo: read the bill at full scale before funding a pilot, prefer the deployable model to the impressive one and value the systems engineers who make AI actually run.

Photo: Google / DeepMind, Future of Go Summit 2017, via CNBC

Joelle Pineau | Reproducible, Reusable, Robust: The Three Rs of a Result That Holds
Enterprise AI AI as a Science

Joelle Pineau | Reproducible, Reusable, Robust: The Three Rs of a Result That Holds

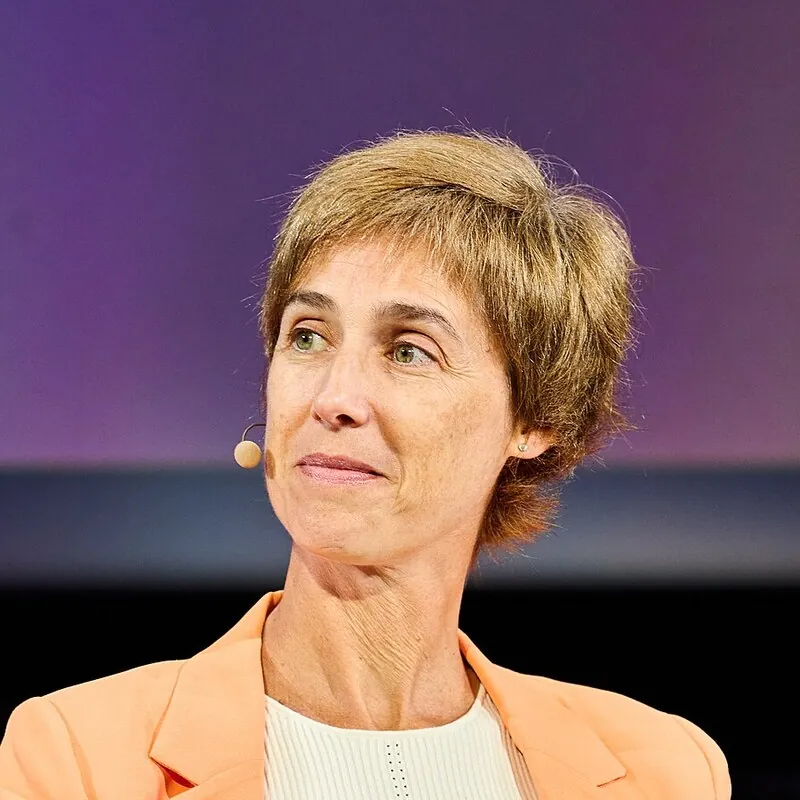
On May 3, 2018, in Vancouver, Joelle Pineau opens the day at ICLR, one of the major machine learning conferences. Her talk carries a three-word title: reproducibility, reusability, robustness. She has worked on reinforcement learning since 1999: a machine acts, receives a score, adjusts. She projects two learning curves, well apart, two algorithms by the look of them. It is the same program with the same settings. Only the random seed changes, the number that fixes the chance of a run. Her only comment: "I think I've made my point." A result is worth something only if it passes three tests. Each one turns into a good practice.

  • Reproducible: count every run. On the two batches of five runs, the standard statistical test concludes there are two different algorithms. We redid the experiment in 2026 on thirty random seeds of PPO, the most widely used algorithm: pitting the five best of ten runs against the five worst fools the test three times in ten. Keeping the three best runs of ten lifts the score by 33% without a single line of code changing. The good practice: report the number of runs and the interval, with nothing sorted out.
  • Reusable: publish what others need to start again. In 2018, of fifty papers, 90% give every setting of their own method and 60% those of the methods they beat. On fifty papers from 2026 we find 18%. She sets master's students the task of reproducing papers submitted to ICLR 2018: one attempt in three recovers the core. At NeurIPS, where she runs the reproducibility program in 2019, the share of accepted papers released with their code goes from under half to 74%. Her checklist is now mandatory.
  • Robust: change the task, change the model. Three small simulated robots give three rankings: one algorithm leads on the running half-cheetah and stalls on the hopping leg. In 2025, a reward drawn at random, unrelated to the right answer, gains a math model 21 points against 29 with the true reward. On other model families it gains nothing. A gain measured on one task or one model can belong to them rather than to the method.

"Science isn't a competitive sport, science is really a collective institution", she said at the end of her talk. The three Rs are its rules of play. She is now Chief AI Officer at Cohere, which sells models to companies: the rule applies to everyone, her included.
The source paper, "Deep Reinforcement Learning that Matters", 2018.

Outcomes: Leave with three good-practice questions to put to any result: does it reproduce (how many runs, which interval, nothing sorted out), can it be reused (code, data and settings published, a baseline tuned with the same care), does it hold when the task or the model changes?

Photo: Gabriel Hutchinson, 2025, CC BY-SA 4.0, Wikimedia Commons

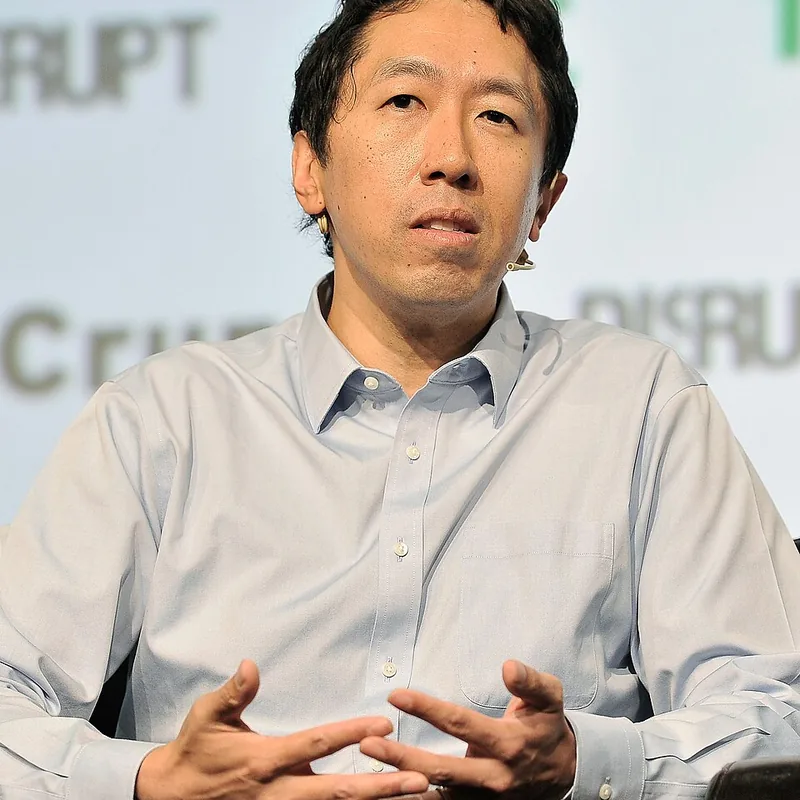
Andrew Ng | The boring eighty percent is the whole job
Enterprise AI

Andrew Ng | The boring eighty percent is the whole job

"Artificial intelligence is the new electricity" went around the world; what gets quoted far less is what he did next, which was to move everyone's attention from the model to the data. While the room stares at the architecture, he looks at the labels: the labelling standard is the real deliverable, a disagreement between two annotators costs more than a point of benchmark and a small scope started on Monday beats a large programme discussed for six months. This portrait defends two ideas a leader should make their own: fix the data before changing the model and make the method circulate instead of keeping it inside one team.

Outcomes: Leave able to demand a written labelling standard before any model budget and to start on a scope small enough to actually ship.

Photo: TechCrunch, CC BY 2.0, Wikimedia Commons

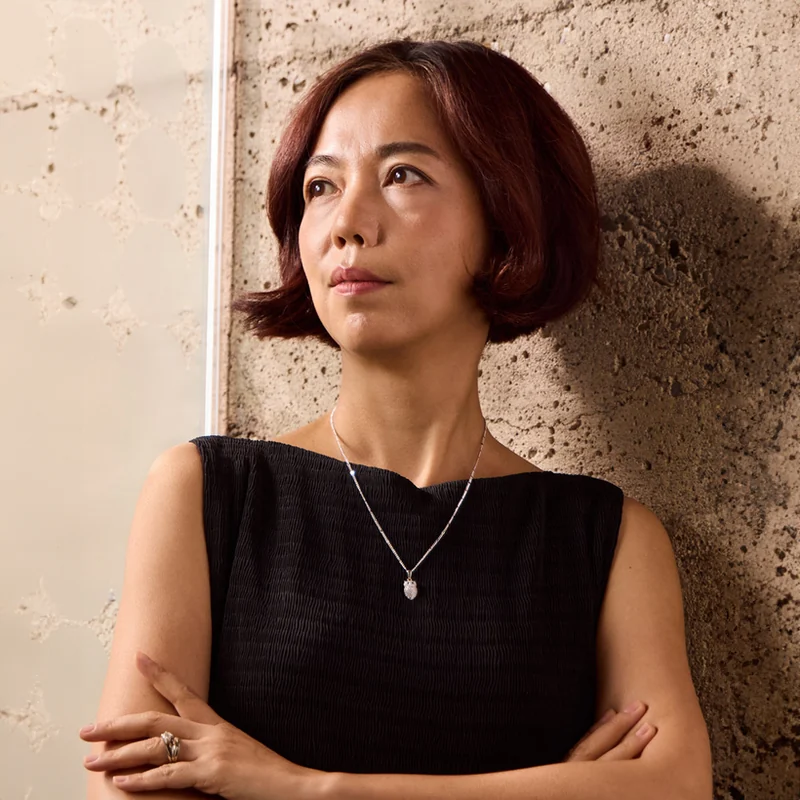
Fei-Fei Li | Benchmarks make fields
Enterprise AI

Fei-Fei Li | Benchmarks make fields

For decades and for lack of resources, artificial intelligence could only play with little data and it took a great deal of human intelligence to solve enormous problems. At the end of the 2000s, Fei-Fei Li's stroke of genius was to bet on massive data, in Computer Vision first. Quantity as never before, but above all the quality of the human annotations that teach the machine: ImageNet and its fourteen million hand-labeled images! The technological lock on images in AI could not hold out for long and we all benefit from it today. This portrait defends two ideas a leader should make their own: data is the real lock and the real competitive advantage, not the algorithm, so audit your annotations before shopping for a better model; and a benchmark can bring a whole field into being, beyond all the images in the world.

Outcomes: Leave able to treat data as the real asset: audit the labels and their provenance before funding a cleverer model, define a benchmark that organizes the work without becoming a target to game and keep the human at the center of what the data is for.

Photo: IEEE Spectrum

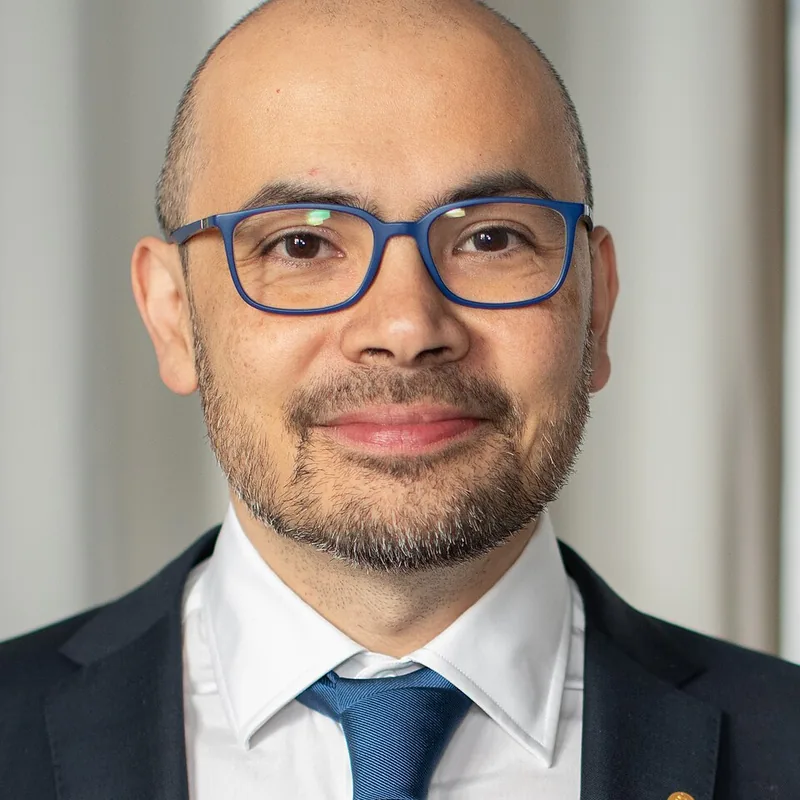
Demis Hassabis | Aim at a problem out of reach, then close it
AI as a Science

Demis Hassabis | Aim at a problem out of reach, then close it

A fifty-year-old scientific problem closed and before that a board game the field thought a decade away: the career holds in two demonstrations. This portrait looks at what a sandbox teaches and what it hides, because a game is honest and the world is not, then at what is worth borrowing from his governance doctrine, aim for a CERN rather than a Manhattan. It defends two ideas a leader should make their own: choose a problem whose success can be verified without an arbiter and say in advance which institution takes on the ambition and its risk.

Outcomes: Leave able to pick a problem whose success verifies itself and to name the institution that takes on the risk of the ambition.

Photo: John Sears, CC BY-SA 4.0, Wikimedia Commons

Cynthia Rudin | Do not explain the black box, build one you can read
Enterprise AI AI with respect to Art, Ethics and Philosophy

Cynthia Rudin | Do not explain the black box, build one you can read

Your model declines the loan. The law requires the letter to name the principal reason, so you buy a module that produces one. Cynthia Rudin asks the question that settles it: is that a reason, or a guess about a reason? Her argument is not a measurement but a piece of logic. If the explanation agreed with the black box everywhere, it would BE the black box and you would throw the model away. So it is wrong somewhere, with nothing to tell you where. On the Broward data, three readable rules resting on two variables reach 66.5% against 66.0% for a proprietary product with 137 questions. This portrait also gives the honest limit, which Rudin states herself: on images, sound or raw text, neural networks keep the advantage. The measured gap elsewhere runs from zero to two points.

Outcomes: Leave able to demand one thing before buying an explanation layer: build the readable model and measure the gap.

Photo: Duke University

Gaël Varoquaux | The licence bill was larger than the hardware bill
Enterprise AI AI as a Science

Gaël Varoquaux | The licence bill was larger than the hardware bill

A physicist wants to automate complex experiments, some of them on zero-gravity parabolic flights and the commercial reference tool of applied science keeps letting him down. He moves to brain imaging and notices an absurdity: the laboratory pays more for software licences than for its computers. So he decides to build something better and free. The trade of data scientist, as a job you can be hired for, came out of that decision as much as out of any paper.

  • "You are over-crediting me", he replied in public when this story was told. The library is a collective artefact. A room that uses it daily has rarely heard the names of the people who maintain it.
  • An interface is a pedagogy. The largest quality gain in applied machine learning was not an algorithm, it was a convention that made the correct procedure the easiest one to type.
  • Try the boring model first. On forty-five tabular datasets, with the hyperparameter search counted inside the budget rather than quietly outside it, tree-based models remained state of the art on medium-sized data.
  • The work is the assembly: joining, encoding and repairing tables whose names are spelled four ways is the project; the model is the last ten percent.
  • Benchmarks are noisier than the decision they inform. A gap smaller than the spread across splits and seeds is not a result.
  • Who pays for the commons? A library everybody depends on and nobody owes anything to is a critical supplier with no contract. Continuity, not virtue, is the argument a finance director understands.

Transparency: I had the privilege of working with probabl.ai
The source paper on tabular data, 2022.

Outcomes: Leave able to demand a fair baseline and a reported spread before any model decision, to budget the data assembly as the project rather than the preamble and to name the open source libraries your production depends on.

Photo: Gaël Varoquaux, CC BY-SA 4.0, Wikimedia Commons

Tamara Atanasoska | Who maintains the instrument your fairness claim rests on
Enterprise AI

Tamara Atanasoska | Who maintains the instrument your fairness claim rests on

"We assessed our model for fairness" passes the committee without anybody asking the two questions that decide whether the sentence means anything: which harm, for which groups and who keeps the tool working. This portrait follows a maintainer of Fairlearn, the open source toolkit many of those claims rest on and takes its teaching from the project's own choices.

  • Harms, not bias. The documentation deliberately avoids the words bias and debiasing and defines unfairness by its impact on people rather than by causes or intent.
  • Four harms, two measurable. Allocation, quality of service, stereotyping, erasure and a manual that says which two the package honestly covers.
  • A table, not a score. Group fairness means your metric computed group by group, with the gap visible and the decision left to whoever signs for it.
  • Fairness is an unobservable construct. Most harm enters when the real problem is translated into a learning task, long before the model.
  • The part nobody puts on a slide. Fifty-two of her sixty-one merged contributions are maintenance, documentation, continuous integration and fixes and the package is downloaded around a hundred thousand times a month by users its maintainers cannot identify, because companies will not discuss their use of fairness tooling.

Outcomes: Leave able to name the harm before the metric, to demand the per-group table rather than a fairness score and to know who maintains the open source tool your compliance depends on.

Photo: Weizenbaum-Institut

Katharine Jarmul | Privacy is a property of the pipeline, not a label on a dataset
Enterprise AI

Katharine Jarmul | Privacy is a property of the pipeline, not a label on a dataset

"We did not keep the data, we only kept the model" is said in good faith in steering committees. It is false: a trained model retains pieces of its training data, most faithfully in the sparse regions where the unusual person lives. That observation is why she moved an entire career from ethics to privacy engineering.

  • The U-turn, on the same stage six years apart. In 2017 she opened a conference on debiasing word vectors, convinced awareness plus technical fixes would do it; in 2023 she returned to say that debiasing has not been shown to work in any meaningful way and that the problem starts before the algorithm.
  • Pseudonymization is not anonymization. Useful, linkable by design and dangerous mostly because it creates a false sense of security that makes teams share data more widely.
  • Governance before technology: documentation, discovery of undocumented data, lineage and versioning, which is the instrument that lets you prove what trained a model and what a deletion request actually removed.
  • Four bridges, four tolls: differential privacy, federated learning, encrypted computation, synthetic data. Each buys something precise and costs something precise. None is private by the mere fact of its name.
  • Privacy built in, not a luxury you pay for, with consent as a product surface: keep data local, federate, anonymise this and not that.

Outcomes: Leave able to stop saying anonymized and say instead which technique, against which attacker, with which residual risk and to treat the model as a copy of the data when you plan deletion, lineage and versioning.

Photo: kjamistan.com

For a tailored course, from half a day to four days: Enterprise AI ↗

Frequently asked questions

Which talks does Deraison offer?

Deraison offers a catalog of 42 thematic talks and 18 portraits of AI figures. The themes range from agentic AI to bias, from large language models to governance. Each portrait argues one thesis, such as “Being early is indistinguishable from being wrong” for Yann LeCun.

Which audiences are Deraison’s talks for?

Deraison’s talks speak to three audiences, each in its own language. Enterprise AI speaks to managers, executives, salespeople and technicians; research AI, to applied-mathematics scientists; AI facing art, ethics and philosophy, to society at large.

Where has Deraison given talks?

Deraison has given talks at the Rennes School of Business EMBA, Mines Paris, Le Wagon, the Institut Henri Poincaré, the French Statistical Society and APIDAYS, among others. Companies such as probabl and Jellysmack have hosted them as well.

How do I organize a talk with Deraison?

To organize a talk with Deraison, book a call: together we pick a theme from the catalog and adapt it to your audience. The quote follows that conversation.

Another question?